

PEAKS® Online 13.5
High-Throughput, Multi-User, and CFR-Compliant Discovery Proteomic LC‑MS/MS Analysis Software
Use PEAKS Online to take advantage of powerful computing resources to perform LC-MS/MS protein and peptide identification and quantification analyses for multiple users at the same time. Our server-based platform allows large datasets to be processed more efficiently with the ability to run on any multi-CPU machine, local cluster or cloud. Whether an industrial, clinical or academic setting, added CFR compliance readiness ensures data integrity, security, and audit preparation! Exclusive to PEAKS Online 13.5 are the Automated Large-Cohort and Real-time Quality Control workflows, providing a comprehensive interface for automated data processing and real-time quality assessment. From DDA to DIA support, PEAKS Online 13.5 offers a comprehensive solution to bring your research to new heights!

High‑Throughput and Multi‑User

Refreshed Intuitive GUI

Peptide and Protein Identification

Superior Quantification

Vendor Neutral Software

Contact Us to add PEAKS Online 13.5 to Your Lab!
Key Features

Distributed System

High-Throughput and Scalable

Dual Interfaces

Streamlined Workflows
Large-Cohort and Real-time QC

Custom Management and Multi-User
DeepNovo Peptidome
DIA Workflow

Sequence Variants
Quantification
Distributed System for High Performance Computing
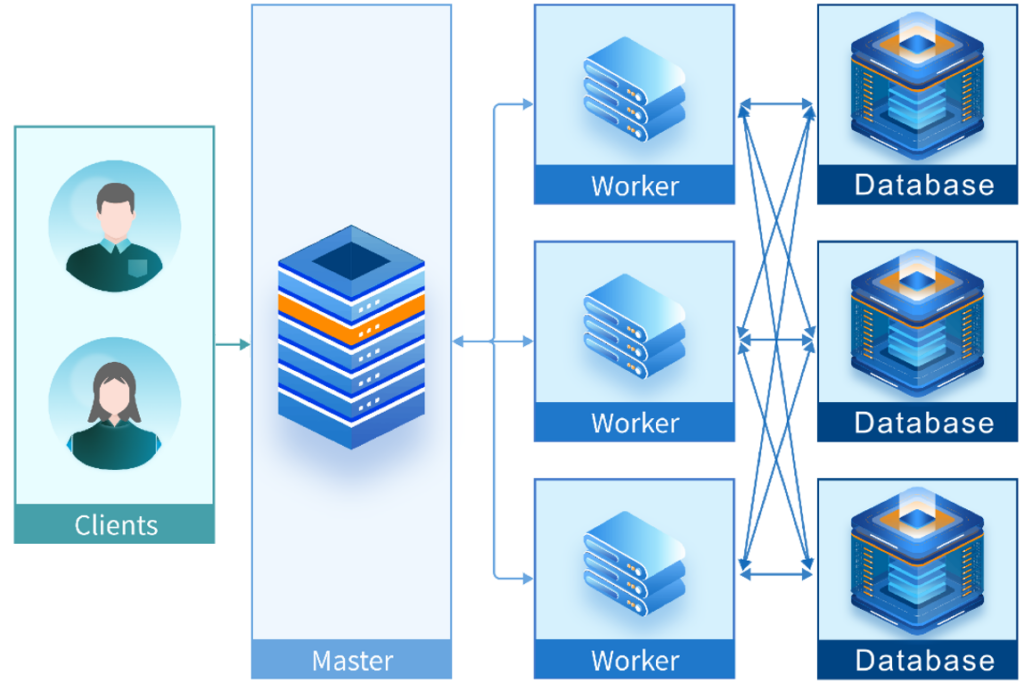
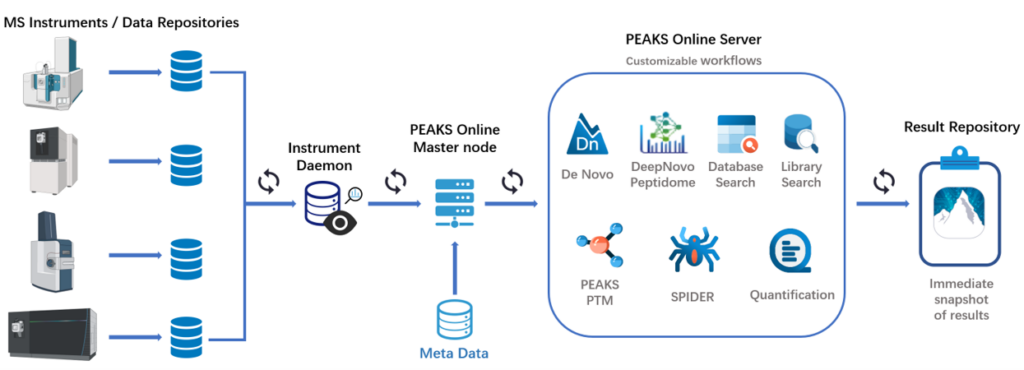
PEAKS Online uses the latest distributed computing technology to achieve high-throughput performance with PEAKS workflows for multiple users on a network. The Master is at the centre of the system; it accepts computing requests from clients and distributes the computing workload to the workers, which perform data processing and computation.
High-Throughput and Scalable
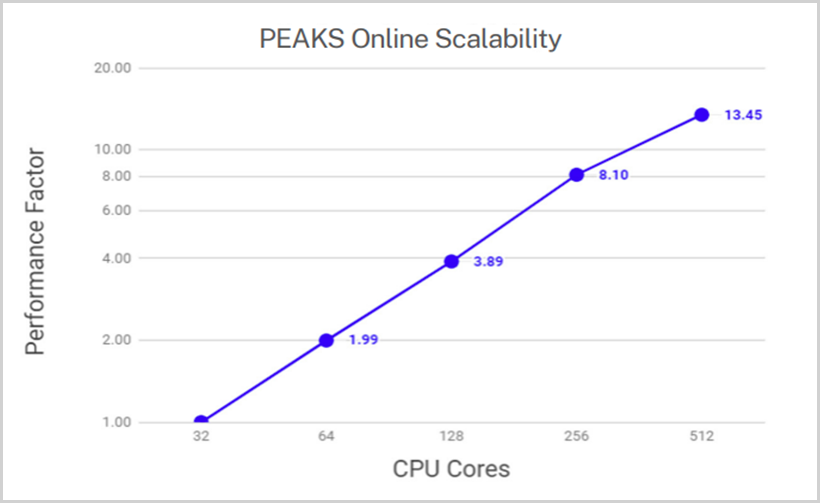
PEAKS Online is a proteomics data analysis platform designed for large scale projects and multiple users to support parallelism at project and data level. Worker and database nodes can be easily added for vertical and horizontal scalability.
Dual Interfaces
In PEAKS Online, dual interfaces are available to ensure easy integration into any proteomics workflow. The Web Client Interface allows users to set up and submit projects visually, as well as review and validate their results. The Client CLI on the other hand can be integrated into existing pipelines to allow for fully automated data processing.
Web Client Interface
Access Administrative Tools
Setup, View and Share Projects
Monitor Ongoing Processes and Modify Priority
Accessible on any OS
Easily setup and access PEAKS projects from any computer, anywhere in the world. With PEAKS Online, users do not need to install any software files to access the server. Just open a web browser, like Google Chrome or Microsoft Edge, to set up PEAKS searches and review the results. When your search task is done, the system will even send you an email to let you know the search is complete.
Client CLI
Automated Batch Data Processing
Define Standardised Workflows
Easily Integrate into Existing Pipelines
Reduce Manual Intervention
The command line interface gives users the ability to fully automate their data analysis. Simply establish standardised workflows so that once data is created in the repository, PEAKS Online will process and generate results instantaneously. Results generated using the Client CLI can be automatically exported into .csv files or viewed using the PEAKS Online Web Client.
Proteome and Peptidome Driven Workflows
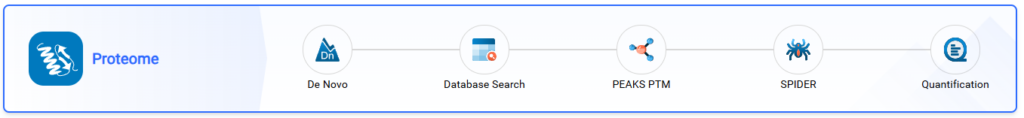
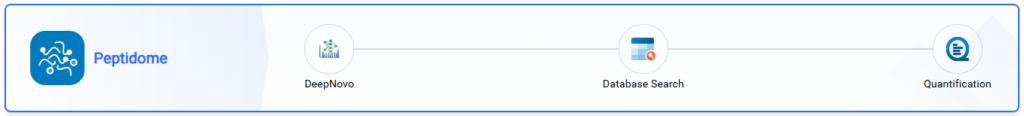
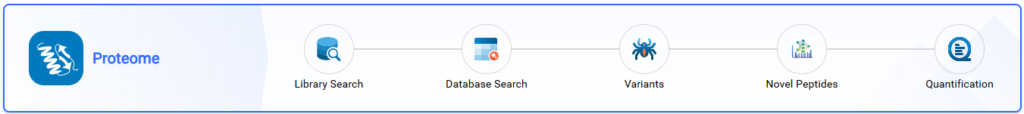
In PEAKS Online the DDA and DIA workflows have been streamlined into two options: Proteome and Peptidome. Users can customise their analysis workflows selecting which step to run or modify. Results are organised into intuitive results nodes, making it easier to interpret, explore and validate your data.
DDA
DIA
Automated Large-Cohort Analyses
Introducing a new project type designed for rapid quality assessment and real-time overview of acquired data. This workflow uses automation of data uploading via instrument daemon, which continuously monitors the data repository for new files and uploads them to the server for analysis. Samples are processed in real time and exported to a predefined location. Additionally, a cohort-level snapshot and summary statistics are dynamically updated throughout the analysis.
Real-time Quality Control
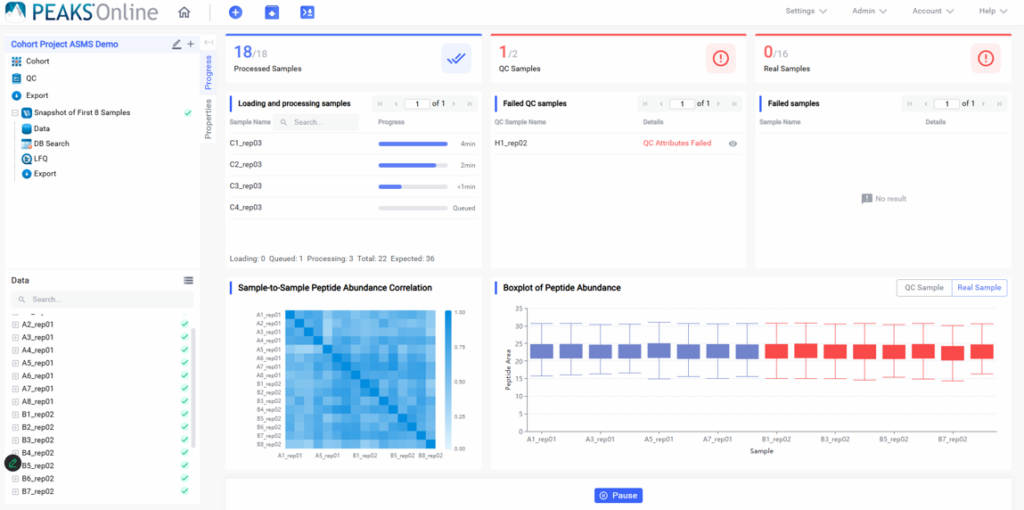
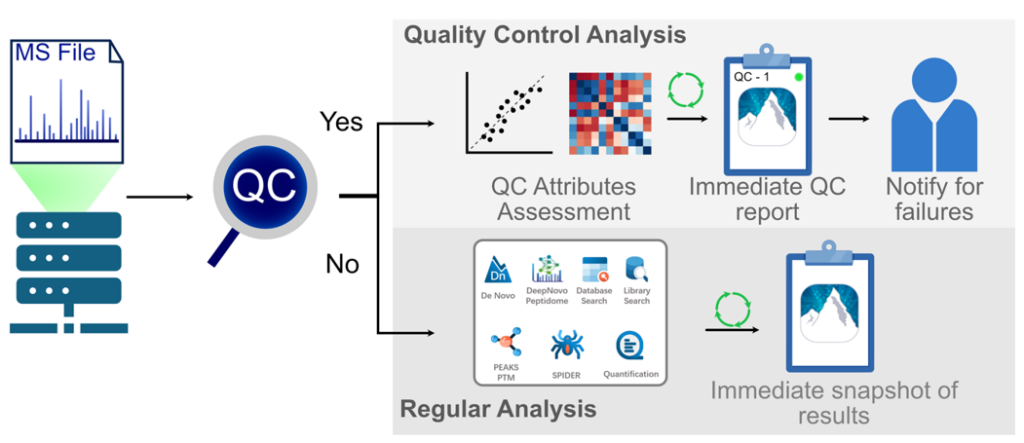
Exclusive to PEAKS Online, this pioneering workflow automatically screens QC samples, assesses technical variation across acquisition, and delivers a comprehensive interface for monitoring data processing status and flagging failed samples in real time. In the event a sample does not meet the defined QC criteria, an automated notification is dispatched to the user.
Custom Management
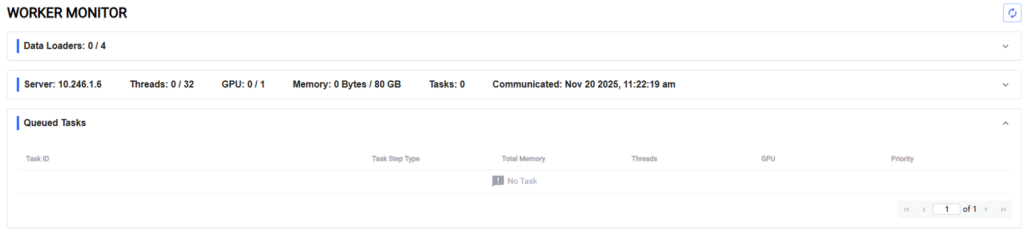
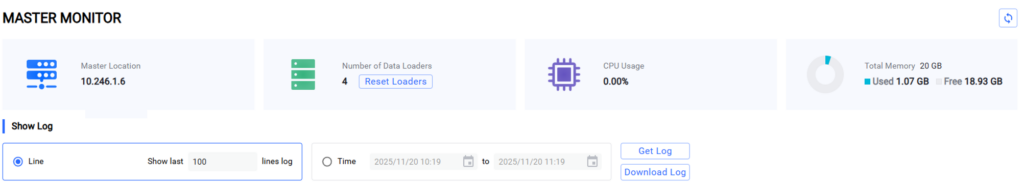
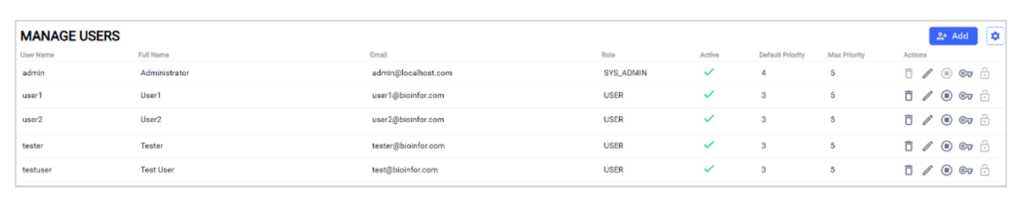
Align your teams' efforts with administrative controls to standardise workflows, databases, PTMs, and quantification methods across your entire team from a single interface. The Worker and Master Monitors provide clear, real-time visibility into active tasks and system communications keeping operations transparent and efficient. Custom sharing capabilities further extend collaboration, allowing users to share projects and configurations such as modifications, enzymes and databases with other users. Easily control administrator and user accounts using the user management page with multi-user access to the PEAKS Online server at the same time.
PEAKS DeepNovo Peptidome
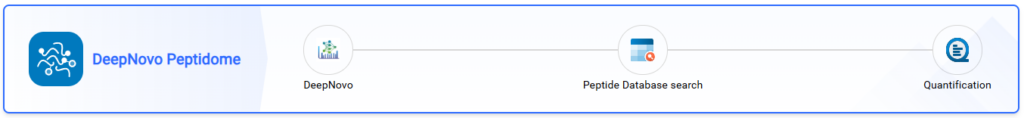
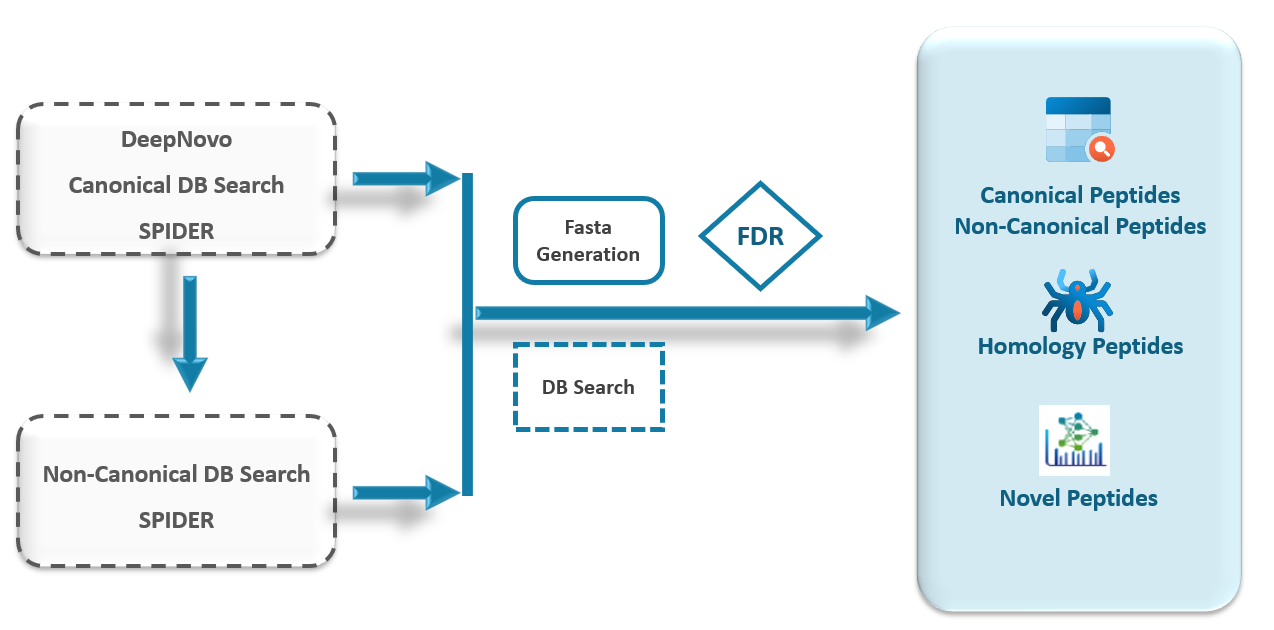
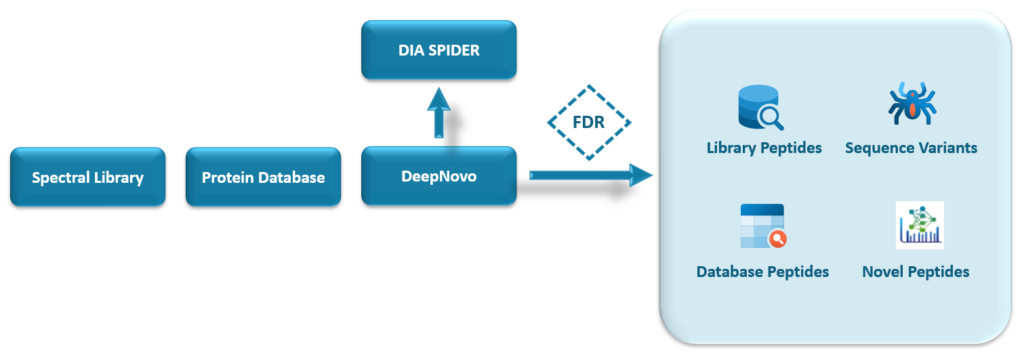
The DeepNovo Peptidome workflow is designed to bridge the gap between proteomics and genomics through the integration of a comprehensive gene table. The DDA workflow supports non-canonical reference sequences allowing for the identification of variant and modified sequences that are often missed by standard canonical reference databases. DIA Peptidome now has support for spectral library and target peptide list to search for target peptides expected to be found in the sample.
DDA Peptidome
DIA Peptidome
Enhanced DIA Proteome Workflow
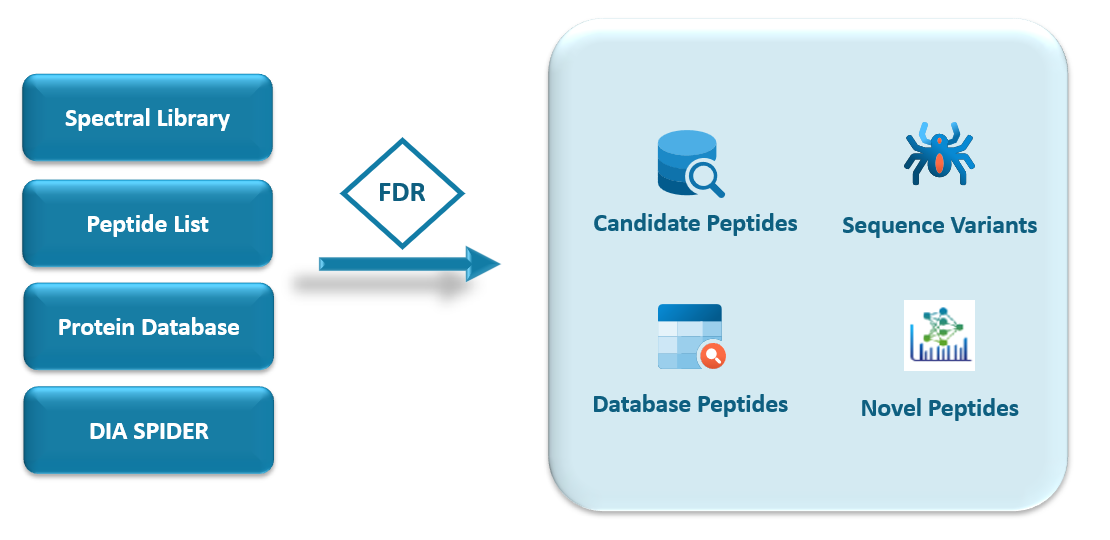
PEAKS offers a robust solution for DIA data analysis. First, an optional library search is performed against a library of previously identified spectra. By estimating the false discovery rate, peptides that pass the filter are saved. MS/MS spectra that don’t match a peptide within the false discovery rate threshold are brought forward to a direct database search. Confident database matches are added to the result. Next, unmatched spectra from the database search are analysed using de novo sequencing. Those peptides passing the average local confidence score will further be subjected to SPIDER algorithm.
Sequence Variants
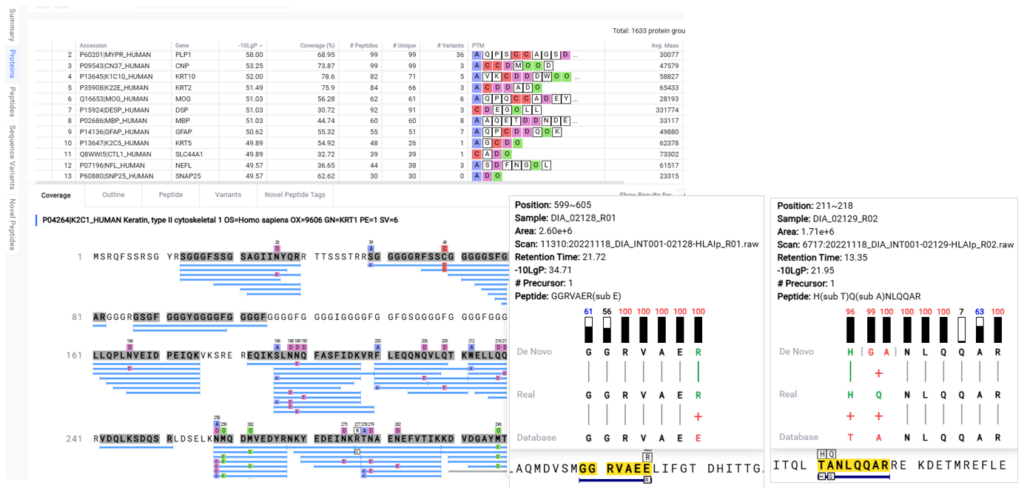
Dive beyond traditional proteomics in PEAKS Online. Uncover sequence variants using SPIDER and Novel Peptides with de novo sequencing.
Quantification
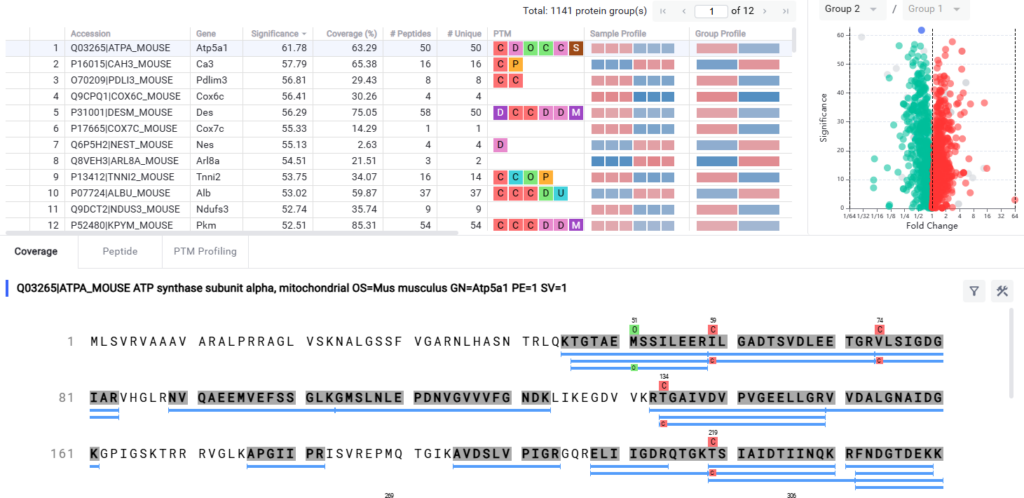
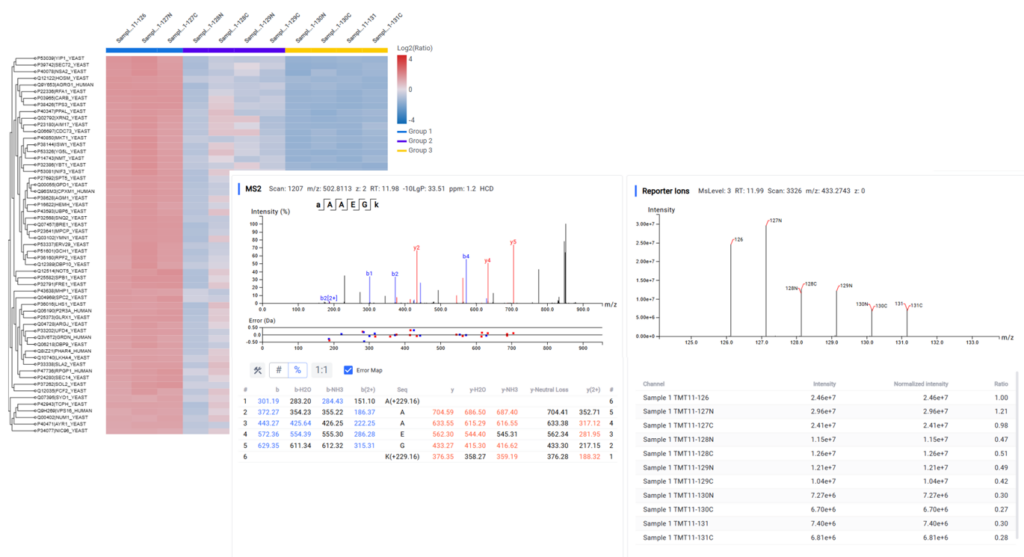
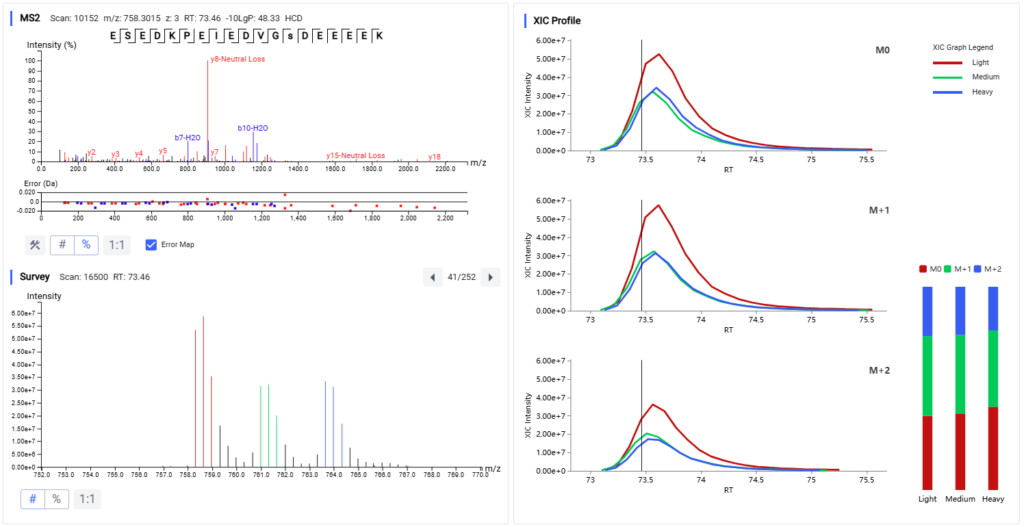
With PEAKS Q module it enables labs to uncover changes in protein expression. Quantify peptide/protein abundances across samples using label-free or labelled quantification techniques. Intuitive result views allow you to assess the quality of the sensitive and reproducible results through heat maps, volcano plots, and extracted ion chromatograms.
Licence Information
PEAKS Online can be scalable to address the requirements of your lab. PEAKS Online is available in licence strengths of 128, 256 and 512 threads with 5-8 users respectively.
Configuration
Base requirements
Recommended configuration for 128 thread licence:
- CPU Threads: 12 (Master) + 32 per data node + 1 per licence thread (172 threads for a single machine 128 thread licence).
- Memory: 12 (Master) + 32 per data node + 2.5 per licence thread (384 GB for a single machine 128 thread licence).
Database requirements
128 or 256 thread licence: Single PostgreSQL node with 2+ TB SSD storage space
512+ thread licence: 2+ PostgreSQL nodes with 2+ TB SSD storage space
GPU Requirements
For running DDA Peptidome or DIA Database Search workflows, it is recommended that your PEAKS Online cluster has access to GPU computation.
The GPU must have NVIDIA CUDA compute capability >= 8.6 with at least 8 GB of dedicated memory.
Furthermore, the GPU needs to be updated to CUDA version 12.6 or later. Please find the CUDA Toolkit installer on NVIDIA's website and install the packaged NVIDIA driver.
Full requirements and installation details can be found in the PEAKS Online 13 Quick User Manual.
References
- Lightbend, Inc. (2011-2019). Akka: Build powerful reactive, concurrent, and distributed applications more easily. https://akka.io/.
- PostgreSQL: The World's Most Advanced Open Source Relational Database. https://www.postgresql.org/
- Xin, L. Qiao R, Chen X, Tran NH, Pan S, Robinoviz S, Bian H, He X, Morse B, Shan B, Li M. A streamlined platform for analyzing tera-scale DDA and DIA mass spectrometry data enables highly sensitive immunopeptidomics. Nat. Commun. 13, 3108 (2022). https://doi.org/10.1038/s41467-022-30867-7